You prompt an AI to build a new feature. It spits out code that looks perfect. You deploy it. Two days later, your mobile app crashes because the JSON structure changed without warning. This is the nightmare of Vibe Coding: speed without stability. When you let Large Language Models (LLMs) drive development, you aren't just writing code; you're generating contracts. If those contracts shift unexpectedly, your entire ecosystem breaks.
The core issue isn't that AI writes bad code. It's that AI doesn't inherently respect the fragile social and technical agreements between a service provider and its consumers. In traditional development, you manually enforce rules. In vibe-coded environments, you need explicit, machine-readable versioning contracts to act as guardrails. These contracts ensure that while the AI iterates rapidly on logic, the external interface remains stable enough for other teams to rely on it.
The Shift from Static Docs to Live Contracts
Historically, API documentation was a static artifact. You wrote a Swagger file, checked it into Git, and hoped developers read it. In vibe-coded workflows, this model fails. The code evolves too fast. Instead, the contract becomes dynamic. Tools now use LLMs to analyze developer prompts and generate OpenAPI 3.0 specifications automatically. Think of this not as documentation, but as a live, machine-readable truth.
For example, if you prompt an AI with "Create a Product schema with id, name, and price," it generates a spec instantly. But here is the catch: if you tweak the prompt next week to add a 'tags' array, the AI regenerates the spec. Without strict versioning rules, this minor addition might inadvertently change how existing clients parse data. The solution lies in treating these generated specs as immutable snapshots tied to specific version numbers. Every regeneration must be diffed against the previous version. If the AI suggests a change that alters the shape of existing data, the system should flag it as a potential breaking change before the code ever hits production.
Applying Semantic Versioning to AI Output
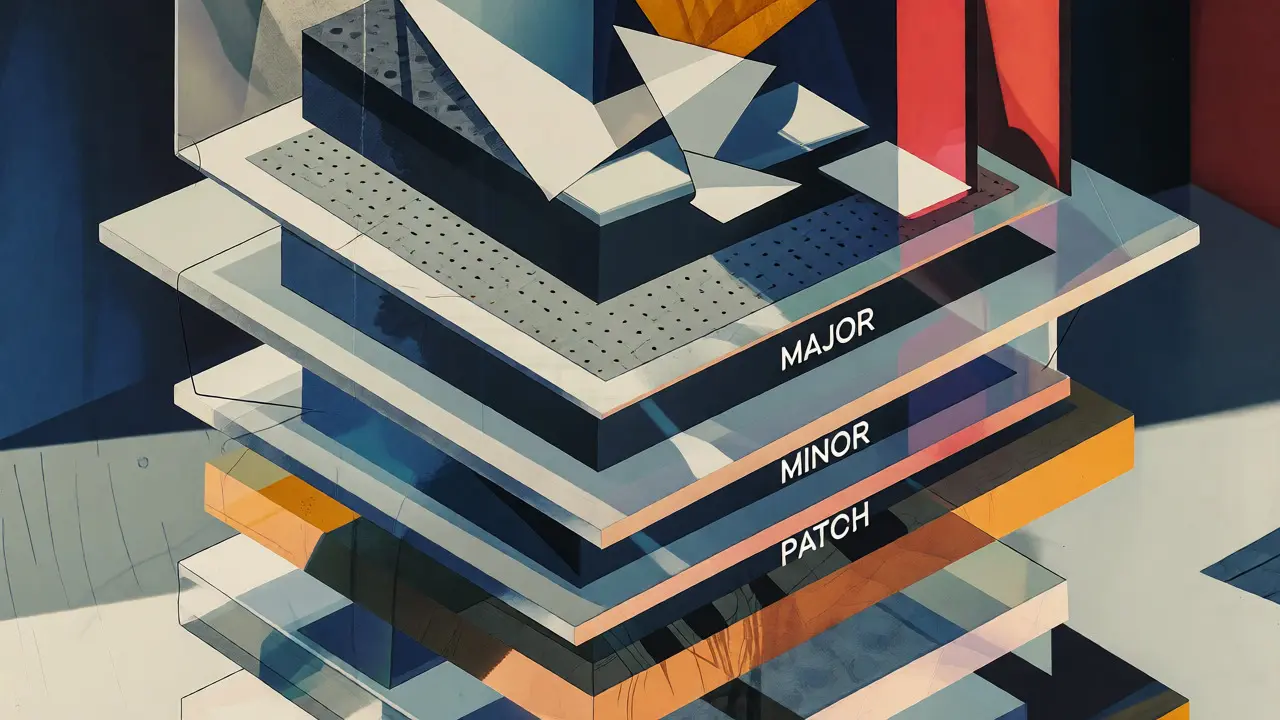
You can't just bump versions randomly. You need to apply Semantic Versioning (SemVer) rigorously to AI-generated outputs. The standard MAJOR.MINOR.PATCH format applies, but the triggers for each increment are different when AI is in the loop.
- PATCH (0.0.X): Use this for bug fixes or internal logic tweaks that don't touch the input/output structure. If the AI optimizes a database query but returns the same JSON, it's a patch. No client action needed.
- MINOR (0.X.0): This is for backward-compatible additions. Did the AI add a new optional field? That's a minor bump. Existing clients ignore the new field; new clients can use it. Crucially, the AI must be instructed to never remove fields during a minor update.
- MAJOR (X.0.0): Reserved for breaking changes. Did the AI rename 'user_id' to 'uuid'? Or change 'price' from a string to a number? That's a major version. Clients must adapt. In vibe coding, major versions should be rare and deliberate, not accidental side effects of a vague prompt.
The danger arises when the AI hallucinates a "minor" improvement that actually breaks compatibility. For instance, changing a null response to an empty object might seem trivial, but it breaks strict parsers. Your validation pipeline needs to catch these subtle shifts.
The Three-Phase Deprecation Protocol
Breaking changes are inevitable, but sudden ones are fatal. To prevent shockwaves, implement a structured deprecation policy. This isn't just a suggestion; it's a hard constraint in your vibe-coding workflow. The process moves through three distinct phases, ensuring consumers have time to migrate.
| Phase | Action | Duration | Client Impact |
|---|---|---|---|
| Notice | Mark feature as deprecated in docs/specs. Provide alternative. | 1 Minor Version | Warning logs only. Code still works. |
| Warning | Trigger explicit runtime warnings. Add migration guides. | 1 Minor Version | Alerts sent to monitoring tools. |
| Removal | Remove the old endpoint or field entirely. | Major Release | Code breaks until updated. |
This timeline forces discipline. You cannot simply ask the AI to "delete the old login method." You must first mark it deprecated, wait two release cycles, and then remove it. This gives mobile apps and third-party integrators time to push updates. If you skip the Notice phase, you're gambling with your users' patience.
Component-Level Versioning Strategies
Not all parts of your API evolve at the same speed. A monolithic version number often creates unnecessary friction. Instead, adopt component-level versioning. Core components like authentication protocols or security toolkits share the main framework version. They are stable and rarely change. However, specialized extensions-like a new recommendation engine module-can have independent version numbers.
This decoupling allows innovation where it matters. You can iterate quickly on experimental features without forcing every consumer to upgrade their entire stack. Just ensure that extension components explicitly declare their compatibility range. For example, "Recommendation Engine v2.1 requires Core API v4.x." This prevents silent incompatibilities where a new extension assumes a feature exists in the core that hasn't been released yet.
Validation Checklists for AI-Generated Code
Treating AI output as "commit-ready" is a recipe for disaster. Hallucinations, deprecated library calls, and license issues slip through. Before any vibe-coded change merges, run a rigorous validation checklist. This acts as your automated safety net.
- Reproduce the Prompt: Store the exact prompt used to generate the code. Context matters. If you can't reproduce the output, you can't debug it.
- Diff the Spec: Compare the new OpenAPI spec against the last stable version. Flag any removed fields or type changes.
- Run Contract Tests: Execute tests that simulate real-world client requests. Ensure that old clients still receive valid responses.
- Scan Dependencies: Use Software Composition Analysis (SCA) tools to check for vulnerable or incompatible libraries introduced by the AI.
- License Check: Verify that any new packages suggested by the AI have compatible licenses. Automated scanning should block ambiguous licenses.
Integrate these checks into pre-commit hooks. If the AI adds a dependency with a restrictive license, the commit fails. If the spec diff shows a breaking change without a major version bump, the merge is blocked. Automation is your best friend here.
Long-Term Support and Release Cadence
Stability is a product feature. Not every team wants to chase the latest AI-generated tweak. Designate Long-Term Support (LTS) versions approximately once a year. LTS releases receive security patches and critical bug fixes for 24 months. This gives regulated industries and large enterprises a predictable window for adoption.
Align your release schedule with this strategy. Patch releases happen monthly as needed. Minor releases occur quarterly. Major releases are considered annually. This predictability helps organizations plan their upgrade cycles. Innovation-focused teams might track the latest minor versions to access new capabilities. Stability-focused teams stick to LTS. Both approaches work, provided the versioning contract is clear about what each stream guarantees.
Governance and RFC Processes
Who decides when a breaking change is acceptable? In vibe-coded environments, governance shouldn't be left to individual developers tweaking prompts. Implement a Request for Comments (RFC) process for significant architectural shifts. Community input helps identify edge cases that the AI might miss. This ensures that breaking changes are deliberate business decisions, not accidental regressions caused by a poorly worded prompt.
Documentation also plays a role here. Capture the rationale behind key decisions. Why did we choose JWT over sessions? Why did we reject OAuth-only? Documenting these choices alongside the code creates a historical record. Future developers (or future AI agents) can understand the context, reducing the risk of reversing well-considered design choices.
What is the biggest risk in vibe-coded API development?
The primary risk is accidental breaking changes due to lack of awareness. AI models optimize for functionality, not necessarily backward compatibility. Without strict versioning contracts, a minor prompt adjustment can alter data structures, crashing downstream clients.
How does OpenAPI 3.0 help prevent breaking changes?
OpenAPI 3.0 provides a machine-readable specification of the API. By auto-generating this spec from AI prompts and comparing it against previous versions, you can programmatically detect changes in endpoints, parameters, and schemas before deployment.
Can I use semantic versioning with AI-generated code?
Yes, and you should. Apply SemVer strictly: PATCH for bug fixes, MINOR for backward-compatible additions, and MAJOR for breaking changes. Automate the enforcement so that AI-generated changes trigger appropriate version bumps based on spec diffs.
What is a deprecation policy in this context?
It is a phased approach to removing features. Features are marked as deprecated (Notice), then warned against (Warning), and finally removed (Removal). This gives consumers time to migrate, preventing sudden service interruptions.
Why is component-level versioning useful?
It allows different parts of the API to evolve at different rates. Core components remain stable, while experimental extensions can iterate quickly. This reduces the blast radius of changes and lets teams adopt new features without upgrading everything.